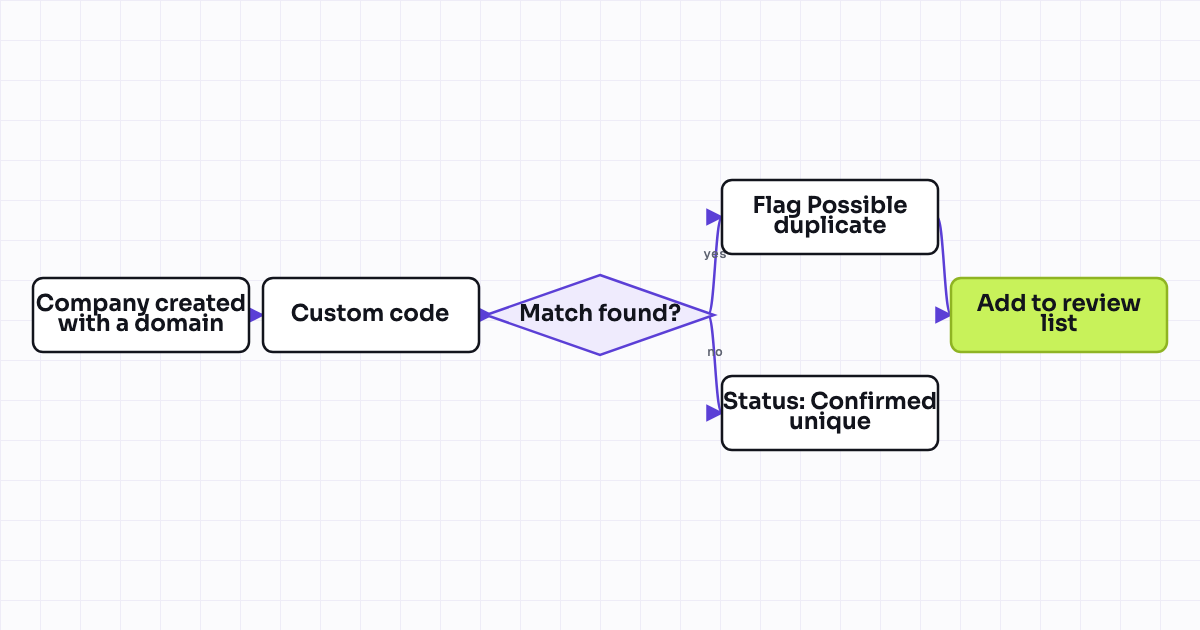
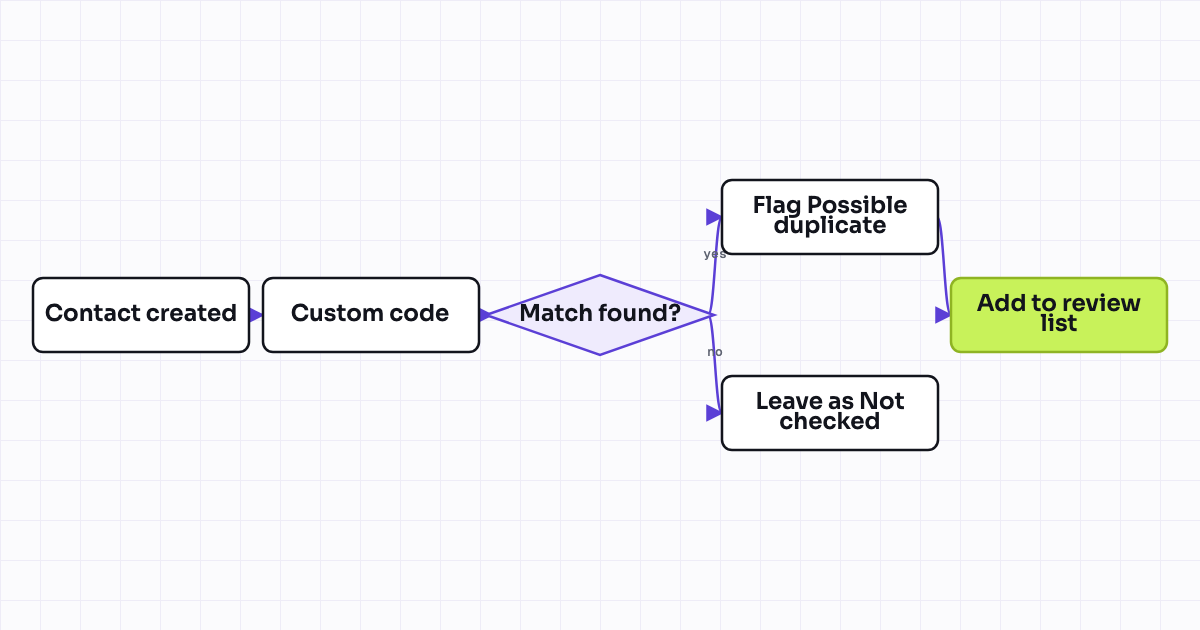
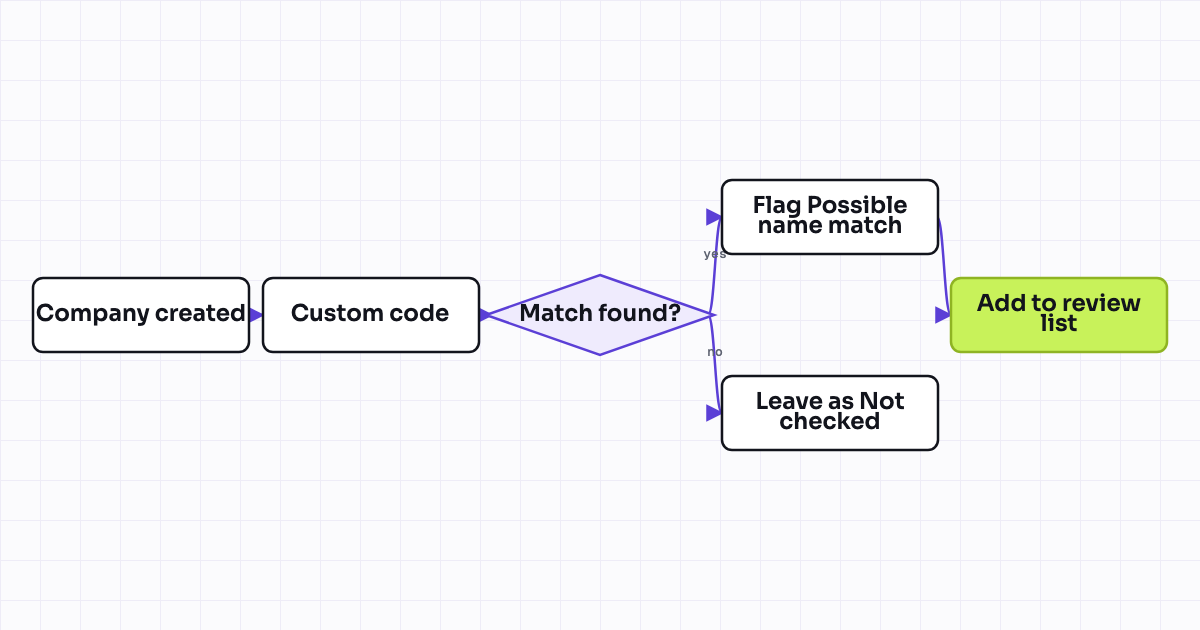
Outcome. Companies with different domains but near-identical names get flagged for review, catching the duplicate pairs that domain-based matching cannot see.
Workflow map
Enrollment, branches and actions at a glance
data-quality-036
flowchart TD
    A[Company created] --> B[Custom code: normalize name, search near-matches]
    B --> C{Match found?}
    C -->|yes| D[Flag Possible name match, store match ID]
    D --> E[Add to review list + create review task]
    C -->|no| F[Leave as Not checked]
When to use it, when not to
- UseUse it alongside data-quality-008 (domain match), as a second pass for companies entered without a domain, or with a domain that differs, an acquired subsidiary using the parent's domain, a rebrand, a typo in the domain field.
- UseUse it when your portal has enough volume of manually-entered or import-sourced companies that name variants like "Acme Inc" and "Acme, Incorporated" actually occur.
- SkipDo not use it as your only duplicate check. Run it as a fallback after the cheaper and more reliable domain match, since name similarity produces more false positives.
- SkipDo not use it expecting a precise fuzzy-matching algorithm. This fiche uses a simple normalize-and-compare approach in custom code, not a dedicated matching library, so tune the similarity threshold against real data before trusting it broadly.
The preview ends here. Six sections are in the library.
counted, not blurred
PrerequisitesEvery property with its label, internal name, type and options, plus the assets the workflow needs before you start.5 items
EnrollmentThe trigger, the criteria exactly as they are ticked in the UI, the re-enrollment rule and the suppression list.4 parts
StepsEach action in order with its parameters, its branches and its delays, written as you tick them.6 numbered actions
Known pitfallsTraps seen in production, each with what breaks and what to do instead.4 pitfalls
Test plan, variants and build specHow to prove it works in a test portal, where to look when it does not, the variants for other objects or tiers, and the YAML build spec.3 variants, 3 sections
FilesThe properties JSON creates the fields in one API call, the workflow JSON documents the build, and the custom coded action ships as a ready-to-paste .js file.PDF, Markdown, JSON, code
Install1 click. The installer creates the properties this spec declares and the workflow itself, switched off, then opens a task for the prerequisites that are assets rather than properties, such as a team, a static list or a marketing email. What it created is listed on the install page.1 click, switched off
Unlock the full library,
149 EUR
or the data quality pack, 39 EUR
One-time, excl. VAT. 30-day refund, no questions asked. Founding prices until 31 October, then 199 and 59 EUR. Includes every spec added later, up to the full 500, and the one-click installer on the full library. Building on client portals? The agency licence at 449 EUR covers unlimited client portals.